Corrected FrontierMath shows AI solving most research-level problems
Epoch AI's audited FrontierMath v2 corrected errors in 42% of problems. On its own runs, the best models solve most of Tiers 1–3 and most of Tier 4, the hardest problems.
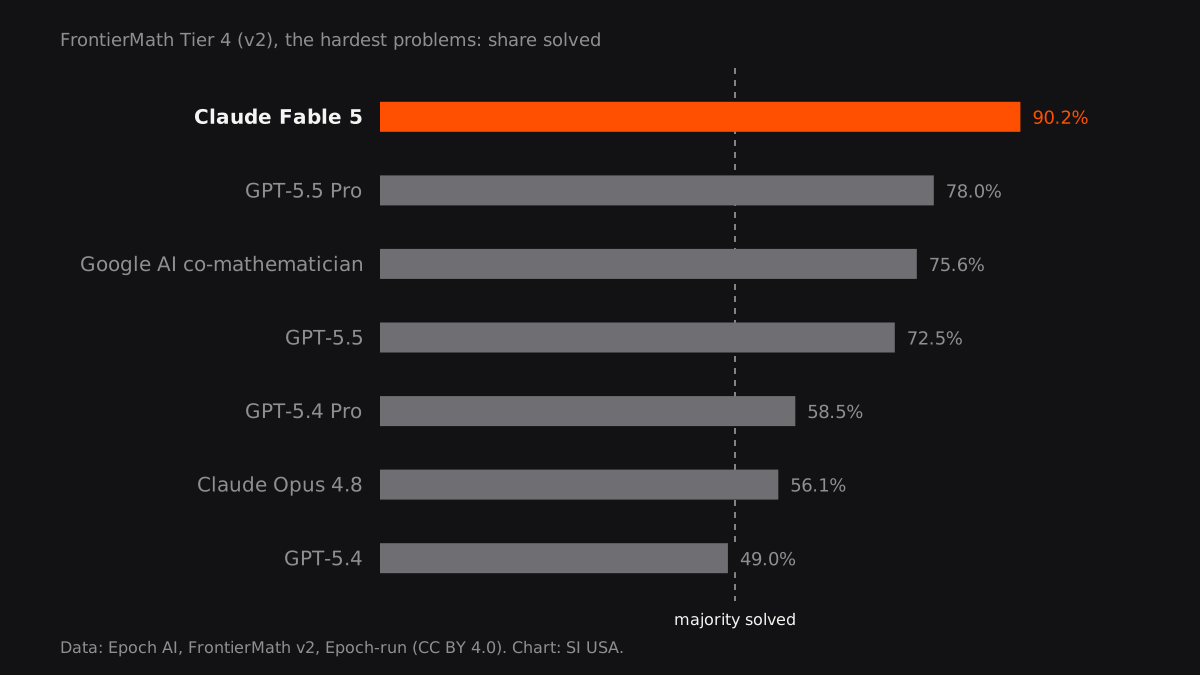
FrontierMath problems are written by working mathematicians and checked automatically. The benchmark crossed the 25% level on Epoch’s own runs in mid-2025. By October 2026 OpenAI’s newest models scored above 90% on both sets, which means the benchmark is close to saturated as a measure of this milestone.
Index treatment. Research-level mathematics moves to 0.5. The next level needs a new theorem accepted by working mathematicians.