OpenAI's GDPval tests models against professionals in 44 occupations
On real work tasks from 44 occupations, graded blind by industry experts, the best model, Claude Opus 4.1, matched or beat the professional's deliverable 47.6% of the time.
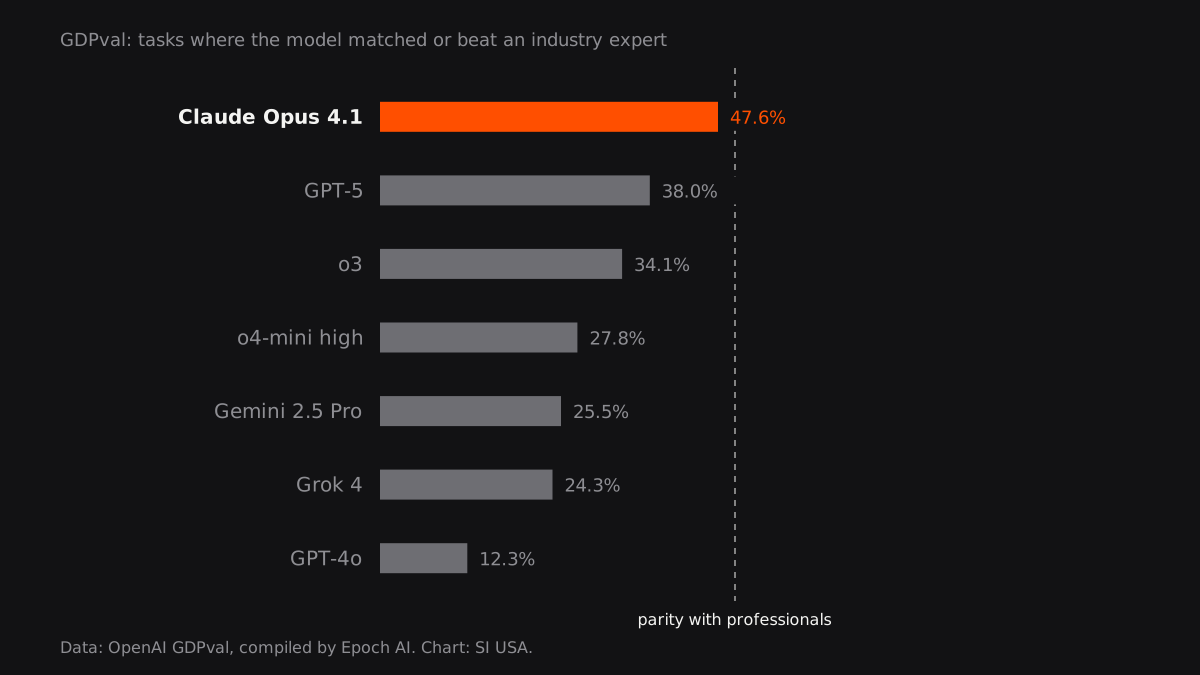
OpenAI built the benchmark and published the gold task set. Its own GPT-5 placed behind Anthropic’s model. The tasks are one-shot deliverables, such as a legal brief or an engineering drawing, not the multi-week projects that make up much real work.
Index treatment. Expert-quality work across occupations moves to 0.5.